Research Writing

Paper pages and research notes organized as a linked map of ideas and projects.

Loading graph...

Select a node on the map to see its details.

Open full map

Selected publications

Putting Transformer Theories to the Test

Awni Altabaa and Tobias Schnabel and Kiran Tomlinson

arXiv preprint, 2026

Abstract · Putting Transformer Theories to the Test

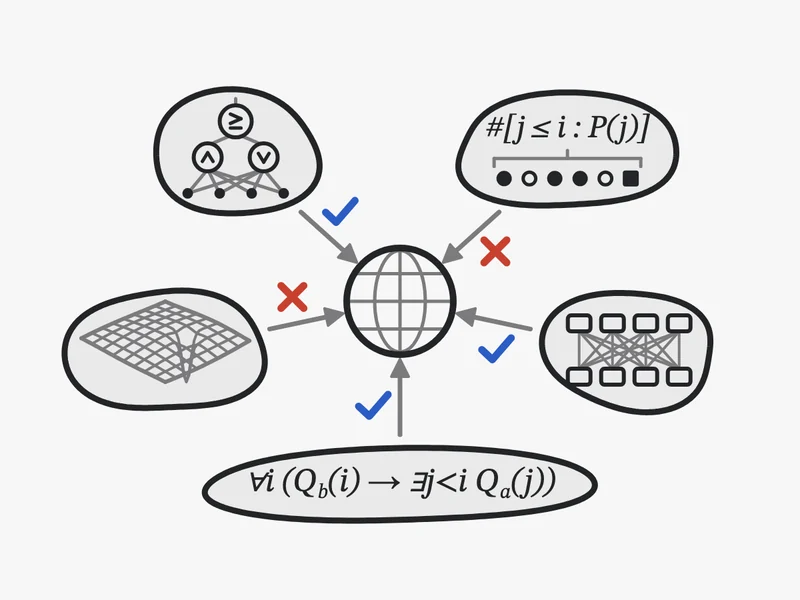
Several formal theories have been developed to characterize the capabilities and limitations of the transformer architecture, each employing different abstractions that capture different features of the architecture. Due to the differences in their underlying assumptions and conceptual frameworks, these theories can disagree in their predictions about what tasks transformers find easy or hard. We map out seven theories of transformer capability (Star-free, AC0, TC0, C-RASP, MPC, BAPO, and Sensitivity) and translate their results into a common matrix of predictions across a suite of tasks covering different computational structures. We provide new theoretical results to complete this matrix. We then evaluate theoretical predictions through controlled experiments measuring in-distribution sample complexity, length generalization, and pretrained language model performance. We find that no single theory explains the observed pattern of successes and failures. When a theory does not capture the transformer behaviors relevant to a task, its predictions break down; for instance, we show that the k-hop induction task is predicted hard by C-RASP because it does not model content-dependent attention, but we train small transformers on this task that length-generalize. Similarly, theories assuming hard attention like AC0 and BAPO predict binary majority to be hard, for which we also find success in practice. Together, our results point to several specific features that a theory of transformers must capture: soft rather than hard attention, dynamic content-dependent retrieval, bounded computation at each position, an account of learnability and inductive biases, and a combination of upper and lower bounds.

BibTeX · Putting Transformer Theories to the Test
@article{altabaa2026transformertheories,
  author = {Awni Altabaa and Tobias Schnabel and Kiran Tomlinson},
  title = {Putting Transformer Theories to the Test},
  journal = {arXiv preprint},
  year = {2026},
  doi = {10.48550/arXiv.2610.32104},
  url = {https://arxiv.org/abs/2610.32104},
  eprint = {2610.32104},
  archiveprefix = {arXiv},
  primaryclass = {cs.LG}
}

Uncovering Latent Reasoning Strategies in Language Models

Awni Altabaa and John Lafferty

arXiv preprint, 2026

Abstract · Uncovering Latent Reasoning Strategies in Language Models

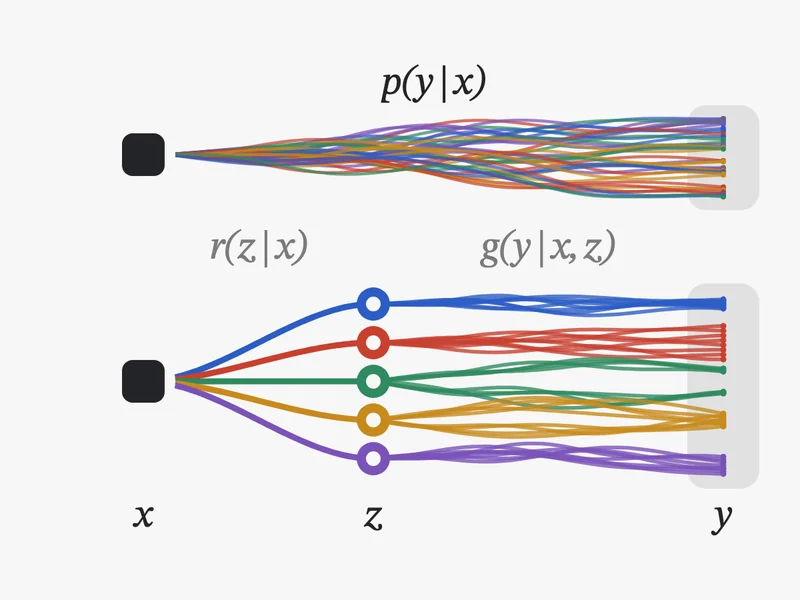
A language model p(y | x) trained on reasoning tasks learns to solve problems via multiple distinct strategies, yet these strategies are implicit and entangled within the model's response distribution. We study the problem of decomposing the response distribution of a given pretrained language model into a structured, strategy-conditioned representation. Specifically, we learn a latent-variable factorization p(y | x) ⇝ (r(z | x), g(y | x, z)), where a router r maps each input to a distribution over latent strategies z and a generator g produces the response conditioned on that strategy. A key challenge is that the generator, initialized from the base model, already represents p(y | x) without using z. Standard variational inference therefore gives the model no incentive to route information through z and can yield a severe form of posterior collapse. To address this, we propose a variational objective that measures fractional information gain relative to the base model's response loss and concentrates reconstruction pressure on tokens with high base model surprisal, encouraging z to encode strategy-relevant response variation. We introduce a benchmark of multi-strategy algorithmic tasks and show that this objective recovers latent codes aligned with distinct reference strategies while preserving the base model's response distribution.

BibTeX · Uncovering Latent Reasoning Strategies in Language Models
@article{altabaa2026uncoveringlatentreasoningstrategies,
  author = {Awni Altabaa and John Lafferty},
  title = {Uncovering Latent Reasoning Strategies in Language Models},
  journal = {arXiv preprint},
  year = {2026},
  url = {https://arxiv.org/abs/2607.17674},
  eprint = {2607.17674},
  archiveprefix = {arXiv},
  primaryclass = {cs.LG}
}

Unlocking Out-of-Distribution Generalization in Transformers via Recursive Latent Space Reasoning

Awni Altabaa and Siyu Chen and John Lafferty and Zhuoran Yang

arXiv preprint, 2025

Abstract · Unlocking Out-of-Distribution Generalization in Transformers via Recursive Latent Space Reasoning

Systematic, compositional generalization beyond the training distribution remains a core challenge in machine learning -- and a critical bottleneck for the emergent reasoning abilities of modern language models. This work investigates out-of-distribution (OOD) generalization in Transformer networks using a GSM8K-style modular arithmetic on computational graphs task as a testbed. We introduce and explore a set of four architectural mechanisms aimed at enhancing OOD generalization: (i) input-adaptive recurrence; (ii) algorithmic supervision; (iii) anchored latent representations via a discrete bottleneck; and (iv) an explicit error-correction mechanism. Collectively, these mechanisms yield an architectural approach for native and scalable latent space reasoning in Transformer networks with robust algorithmic generalization capabilities. We complement these empirical results with a detailed mechanistic interpretability analysis that reveals how these mechanisms give rise to robust OOD generalization abilities.

BibTeX · Unlocking Out-of-Distribution Generalization in Transformers via Recursive Latent Space Reasoning
@article{altabaa2025unlockingoutofdistributiongeneralizationtransformers,
  author = {Awni Altabaa and Siyu Chen and John Lafferty and Zhuoran Yang},
  title = {Unlocking Out-of-Distribution Generalization in Transformers via Recursive Latent Space Reasoning},
  journal = {arXiv preprint},
  year = {2025},
  url = {https://arxiv.org/abs/2510.14095},
  eprint = {2510.14095},
  archiveprefix = {arXiv},
  primaryclass = {cs.LG}
}

CoT Information: Improved Sample Complexity under Chain-of-Thought Supervision

Awni Altabaa and Omar Montasser and John Lafferty

Neural Information Processing Systems (NeurIPS), spotlight, 2025

Abstract · CoT Information: Improved Sample Complexity under Chain-of-Thought Supervision

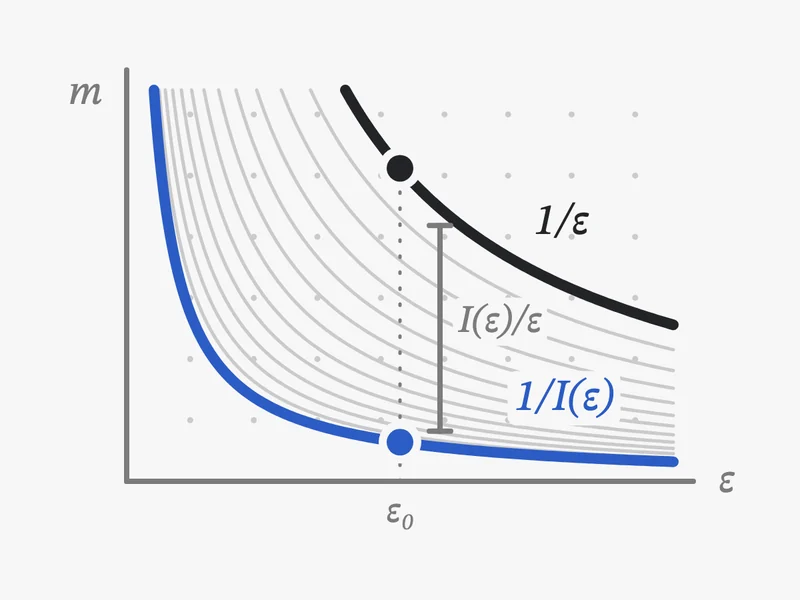
Learning complex functions that involve multi-step reasoning poses a significant challenge for standard supervised learning from input-output examples. Chain-of-thought (CoT) supervision, which provides intermediate reasoning steps together with the final output, has emerged as a powerful empirical technique, underpinning much of the recent progress in the reasoning capabilities of large language models. This paper develops a statistical theory of learning under CoT supervision. A key characteristic of the CoT setting, in contrast to standard supervision, is the mismatch between the training objective (CoT risk) and the test objective (end-to-end risk). A central part of our analysis, distinguished from prior work, is explicitly linking those two types of risk to achieve sharper sample complexity bounds. This is achieved via the CoT information measure, which quantifies the additional discriminative power gained from observing the reasoning process. The main theoretical results demonstrate how CoT supervision can yield significantly faster learning rates compared to standard E2E supervision.

BibTeX · CoT Information: Improved Sample Complexity under Chain-of-Thought Supervision
@article{altabaa2025cotinformation,
  author = {Awni Altabaa and Omar Montasser and John Lafferty},
  title = {CoT Information: Improved Sample Complexity under Chain-of-Thought Supervision},
  journal = {Neural Information Processing Systems (NeurIPS), spotlight},
  year = {2025},
  url = {https://arxiv.org/abs/2505.15927},
  eprint = {2505.15927},
  archiveprefix = {arXiv},
  primaryclass = {stat.ML}
}

Disentangling and Integrating Relational and Sensory Information in Transformer Architectures

Awni Altabaa and John Lafferty

International Conference on Machine Learning (ICML), 2025

Abstract · Disentangling and Integrating Relational and Sensory Information in Transformer Architectures

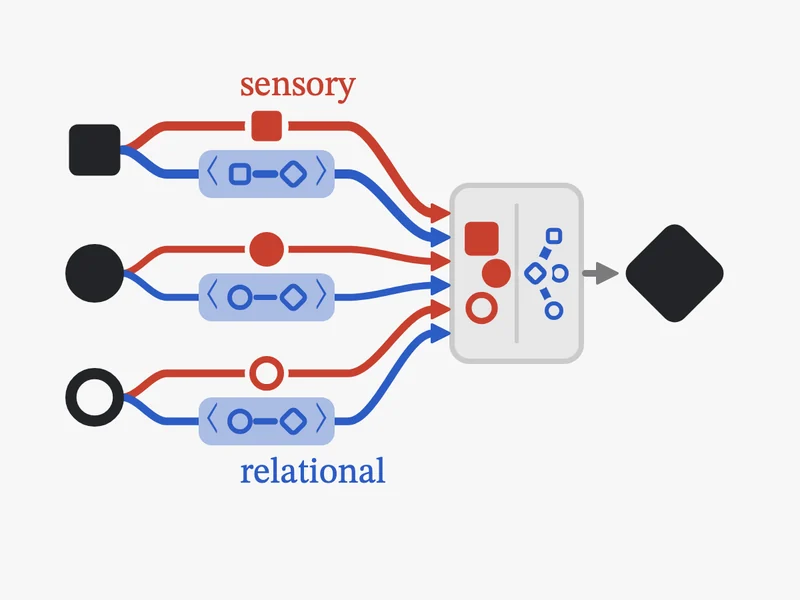
Relational reasoning is a central component of generally intelligent systems, enabling robust and data-efficient inductive generalization. Recent empirical evidence shows that many existing neural architectures, including Transformers, struggle with tasks requiring relational reasoning. In this work, we distinguish between two types of information: sensory information about the properties of individual objects, and relational information about the relationships between objects. While neural attention provides a powerful mechanism for controlling the flow of sensory information between objects, the Transformer lacks an explicit computational mechanism for routing and processing relational information. To address this limitation, we propose an architectural extension of the Transformer framework that we call the Dual Attention Transformer (DAT), featuring two distinct attention mechanisms: sensory attention for directing the flow of sensory information, and a novel relational attention mechanism for directing the flow of relational information.

BibTeX · Disentangling and Integrating Relational and Sensory Information in Transformer Architectures
@article{altabaa2024disentangling,
  author = {Awni Altabaa and John Lafferty},
  title = {Disentangling and Integrating Relational and Sensory Information in Transformer Architectures},
  journal = {International Conference on Machine Learning (ICML)},
  year = {2025},
  url = {https://arxiv.org/abs/2405.16727},
  eprint = {2405.16727},
  archiveprefix = {arXiv},
  primaryclass = {cs.LG}
}

On the Role of Information Structure in Reinforcement Learning for Partially-Observable Sequential Teams and Games

Awni Altabaa and Zhuoran Yang

Neural Information Processing Systems (NeurIPS), 2024

Abstract · On the Role of Information Structure in Reinforcement Learning for Partially-Observable Sequential Teams and Games

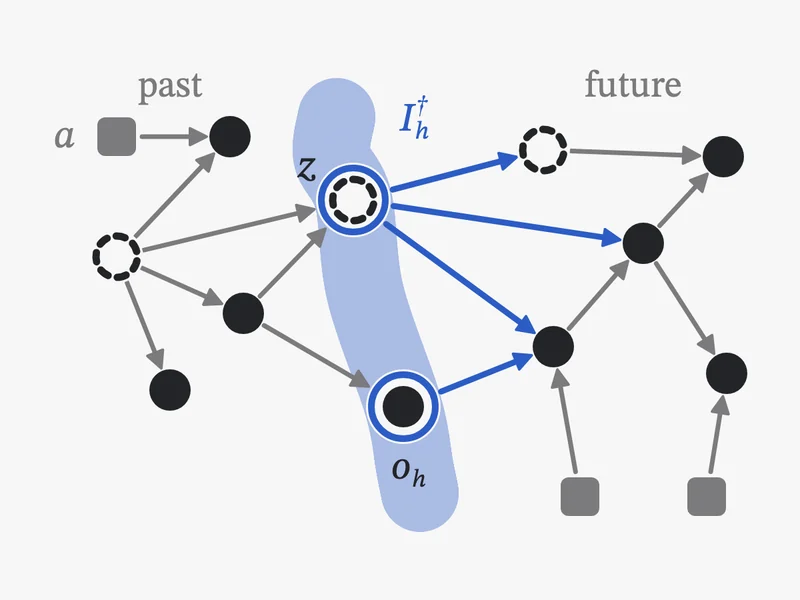
In sequential decision-making problems, the information structure describes the causal dependencies between system variables, encompassing the dynamics of the environment and the agents' actions. Classical models of reinforcement learning assume a restricted and highly regular information structure, while more general models like predictive state representations do not explicitly model the information structure. By contrast, real-world sequential decision-making problems typically involve a complex and time-varying interdependence of system variables, requiring a rich and flexible representation of information structure. In this paper, we formalize a novel reinforcement learning model which explicitly represents the information structure.

BibTeX · On the Role of Information Structure in Reinforcement Learning for Partially-Observable Sequential Teams and Games
@article{altabaaRoleInformationStructure2024,
  author = {Awni Altabaa and Zhuoran Yang},
  title = {On the Role of Information Structure in Reinforcement Learning for Partially-Observable Sequential Teams and Games},
  journal = {Neural Information Processing Systems (NeurIPS)},
  year = {2024},
  doi = {10.48550/arXiv.2403.00993},
  url = {https://arxiv.org/abs/2403.00993},
  eprint = {2403.00993},
  archiveprefix = {arXiv},
  primaryclass = {cs, stat}
}
All publications

Recent writing