CoT Information: Improved Sample Complexity under Chain-of-Thought Supervision

A statistical learning theory for chain-of-thought supervision, centered on a CoT information measure that governs sample complexity.

arXiv Slides Poster Publisher

Learning to Think: The Chain-of-Thought Advantage

Chain-of-thought (CoT) training has quickly become central to the reasoning breakthroughs of large language models. By supervising models not only on final answers but also on the intermediate reasoning steps, CoT training teaches them how to think, not just what to predict. This shift has enabled LLMs to tackle problems that require multi-step reasoning—tasks where conventional models trained end-to-end often fail.

We can see this difference in action when both models attempt the same problem.

ChatGPT 5 Instant wrong
Which number is larger, 9.9 or 9.10?

A: 9.10

ChatGPT 5 Thinking correct
Which number is larger, 9.9 or 9.10?

Thought for 7s

The difference between 9.9 and 9.10 is subtle but important. In decimal notation, trailing zeros don’t change the value, so 9.10 is the same as 9.1. But in versioning, 9.10 could be considered larger than 9.9. For a basic comparison, 9.90 is greater than 9.1, so 9.9 is larger. I’ll keep it clear and concise.

A: 9.9

ChatGPT 5 Instant wrong
A forest has 1000 trees. Each year, loggers cut down half of the trees remaining at the start of the year. In the same year, conservationists plant 100 new trees at the end of the year. After this process repeats for two years, how many trees are in the forest?

A: 350

ChatGPT 5 Thinking correct
A forest has 1000 trees. Each year, loggers cut down half of the trees remaining at the start of the year. In the same year, conservationists plant 100 new trees at the end of the year. After this process repeats for two years, how many trees are in the forest? Think step by step.

Thought for 23s

A: 400 (Year 1: 1000 → 500 → 600; Year 2: 600 → 300 → 400)

ChatGPT 5 Instant wrong
Suppose x+2y−z=4x + 2y - z = 4, −3x−y+z=10-3x - y + z = 10, 4x+y−2z=154x + y - 2z = 15. Solve for x,y,zx, y, z.

A: x=3, y=2, z=4x = 3,\ y = 2,\ z = 4

ChatGPT 5 Thinking correct
Suppose x+2y−z=4x + 2y - z = 4, −3x−y+z=10-3x - y + z = 10, 4x+y−2z=154x + y - 2z = 15. Solve for x,y,zx, y, z.

End of reasoning

… Now use (3): 4x+y−2z=154x + y - 2z = 15. 4x+(2x+14)−2(5x+24)=15⇒6x+14−10x−48=15⇒−4x−34=15⇒…4x + (2x + 14) - 2(5x + 24) = 15 \Rightarrow 6x + 14 - 10x - 48 = 15 \Rightarrow -4x - 34 = 15 \Rightarrow \dots Then y=2x+14=−212y = 2x + 14 = -\tfrac{21}{2}, z=5x+24=−1494z = 5x + 24 = -\tfrac{149}{4}.

A: x=−494, y=−212, z=−1494x = -\tfrac{49}{4},\ y = -\tfrac{21}{2},\ z = -\tfrac{149}{4}

ChatGPT 5 Instant, prompted to respond instantly, guesses the wrong answer. ChatGPT 5 Thinking produces the correct answer after reasoning step-by-step.

These vignettes summarize the main observation: CoT supervision dramatically improves reasoning accuracy.

In this work, we develop a learning-theoretic framework to formalize and quantify this statistical advantage. We are motivated by the following key question:

  • When does CoT supervision reduce sample complexity compared to end-to-end supervision, and by how much?
  • How do we quantify the added information provided by CoT traces?
  • What statistical upper bounds and lower bounds govern learning with CoT supervision?

Part I: The Role of Chain-of-Thought Supervision in Building LLMs

Before diving into theory, it’s useful to recall where chain-of-thought supervision fits in the modern large language model training pipeline.
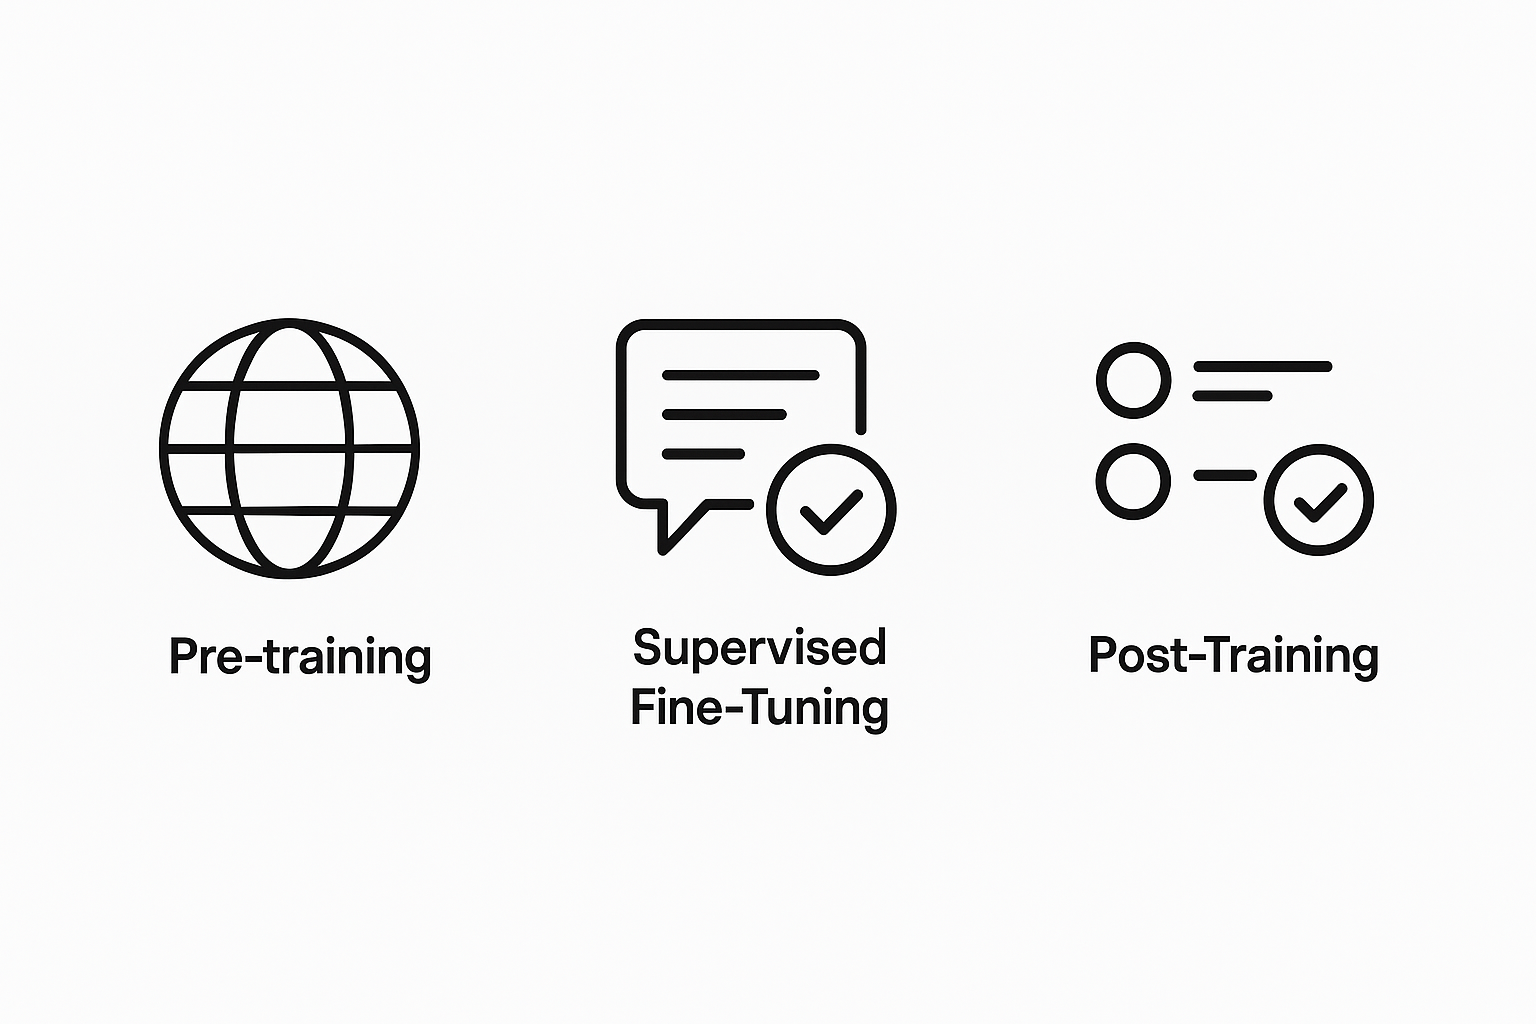
Three-stage pipeline for building large language models.
A hitchhiker’s guide to building an LLM.

Step 1: Pre-training (foundation modeling).

  • Goal. Learn broad world knowledge and language ability.
  • Data + Objective. Next-token prediction over internet-scale text.

Step 2: Supervised fine-tuning.

  • Goal. Teach the model to follow instructions and reason through tasks step-by-step.
  • Data + Objective. High-quality human demonstrations in a Q/A format, often with chain-of-thought rationales.

Step 3: Post-training (alignment and preference optimization).

  • Goal. Align model behavior with human preferences, enforce safety policies, and enable tool use or function calling.
  • Data + Objective. Human preference data (e.g., RLHF/DPO), supervised traces for tool use, synthetic or augmented data, etc.

CoT supervision plays a pivotal role in how LLMs learn to reason, follow instructions, and generalize beyond pattern matching.

CoT supervision primarily lives in Step 2. We abstract away the mechanics of trace collection and instead ask: What statistical advantage does CoT training confer relative to vanilla input–output supervision?

Where Do CoT Traces Come From?

CoT traces can be collected in several ways:

  • Human-authored: experts or trained annotators, or mined from educational content (textbook solutions, etc.)1 Training Verifiers to Solve Math Word Problems Karl Cobbe, Vineet Kosaraju, et al.arXiv preprint · 2021 arXiv .
  • Model-generated: prompt an existing model, and filter using self-consistency or self-verification2 Self-Consistency Improves Chain of Thought Reasoning in Language Models Xuezhi Wang, Jason Wei, et al.International Conference on Learning Representations (ICLR) · 2023 arXiv 3 STaR: Bootstrapping Reasoning With Reasoning Eric Zelikman, Yuhuai Wu, et al.Neural Information Processing Systems (NeurIPS) · 2022 arXiv 4 Let's Verify Step by Step Hunter Lightman, Vineet Kosaraju, et al.International Conference on Learning Representations (ICLR) · 2024 arXiv .
  • Hybrid: generate with a model and let humans filter/rate/edit.
  • Programmatic synthesis: feasible for some domains with algorithmic generators.

In what follows, we abstract away the mechanics of obtaining CoT traces or their format (e.g., natural language or otherwise). We assume the CoT dataset exists, and ask: What statistical advantage does CoT training confer relative to vanilla input–output supervision?

Part II: Formalizing Learning with CoT Supervision

A Quick Refresher on Classical Supervised Learning

To provide context and intuition, let us briefly review the classical supervised learning setup.

We aim to learn h⋆:X→Y\hstar: \calX \to \calY inside a hypothesis class H⊂YX\calH \subset \calY^{\calX}. We observe labeled examples (xi,yi)(x_i, y_i) with xi∼i.i.d.Dx_i \simiid \calD and yi=h⋆(xi)y_i = \hstar(x_i) (realizable setting). A learner

A:S={(xi,yi)}i=1m⟼h^\calA: S = \{(x_i, y_i)\}_{i=1}^m \longmapsto \hhat

seeks small prediction error

R(h^):=Px∼D[h^(x)≠y]≤ε.\calR(\hhat) := \probunder{x \sim \calD}{\hhat(x) \neq y} \leq \epsilon.

Distinguishing two hypotheses h1h_1, h2h_2 requires observing an input xx for which they disagree. If Px∼D[h1(x)≠h2(x)]=ε\probunder{x \sim \calD}{h_1(x) \neq h_2(x)} = \epsilon, then Θ(1/ε)\Theta(1 / \epsilon) samples are needed. Extending via a union bound yields the familiar sample complexity O(log⁡∣H∣/ε)\bigO(\log |\calH| / \epsilon).

Here, the denominator ε\epsilon reflects the information per sample. For example, under noise (agnostic setting), where there is less “information” per sample, the rate is weakened to 1/ε21/\epsilon^2. Similarly, under low-noise assumptions, it is possible to interpolate between 1/ε1/\epsilon and 1/ε21/\epsilon^2. We will see that the effect of CoT supervision appears precisely in this denominator, capturing the extra information per sample provided through observing the CoT trace.

Why End-to-End Supervision Struggles

For tasks involving long-form or multi-step reasoning—mathematics, logical deduction, or code generation—the target function h⋆\hstar is highly complex. Observing only (x,y)(x, y) pairs reveals little about its internal computation, making learning statistically inefficient. The result is a steep sample complexity curve: vast data are required to approximate the underlying reasoning process.

Strengthening the Signal: CoT Supervision

CoT training enriches supervision by exposing how a model arrives at its answer. Instead of learning solely from (x,y)(x, y), the learner also observes a reasoning trace zz.

Suppose h1h_1, h2h_2 emit both an answer y=he2e(x)y = \hete{h}(x) and a reasoning trace z=hCoT(x)z = \hcot{h}(x). The two hypotheses can now be distinguished if they differ in either the final output or the intermediate CoT computational trace. Let us denote this probability of disagreeement as I(ε)I(\epsilon), thinking of it as a modification of the end-to-end disagreement probability ε\epsilon above:

I(ε):=Px∼D[h1e2e(x)≠h2e2e(x) OR h1CoT(x)≠h2CoT(x)]≥ε.I(\epsilon) := \probunder{x \sim \calD}{\hete{h_1}(x) \neq \hete{h_2}(x) \text{ OR } \hcot{h_1}(x) \neq \hcot{h_2}(x)} \geq \epsilon.

The additional information I(ε)I(\epsilon) makes hypotheses easier to distinguish—reducing the sample requirement from O(1/ε)\bigO(1/\epsilon) to O(1/I(ε))\bigO(1/I(\epsilon)). Intuitively, a single CoT-labeled example can be worth many ordinary examples in terms of information gained.

CoT Hypothesis Classes and CoT-PAC Learning

Formally, a CoT hypothesis class is a family H⊂(Y×Z)X\calH \subset (\calY \times \calZ)^{\calX} of functions h:X→Y×Zh: \calX \to \calY \times \calZ. We denote:

  • he2e:X→Y\hete{h}: \calX \to \calY is the end-to-end restriction.
  • hCoT:X→Z\hcot{h}: \calX \to \calZ is the CoT restriction.

A CoT learner observes a dataset of triples (xi,yi,zi)(x_i, y_i, z_i) and outputs a predictor in YX\calY^{\calX}. We say the class is PAC-learnable under CoT supervision with sample complexity mH,D(ε,δ)m_{\mathcal{H}, \mathcal{D}}(\epsilon, \delta) if

PS∼Dm[Px,y∼Dx,y[A(S)(x)≠y]≤ε]≥1−δwhenever m≥mH,D(ε,δ).\probunder{S \sim \calD^m}{\probunder{x,y \sim \calD_{x,y}}{\calA(S)(x) \neq y} \leq \epsilon} \geq 1 - \delta \quad \text{whenever } m \geq m_{\calH, \calD}(\epsilon, \delta).

Note that while the learner observes both final outputs and CoT traces for each example, the evaluation metric is the end-to-end error.

Part III: Statistical Guarantees and CoT Information

Central Analytical Challenge: Training–Testing Asymmetry

The central analytical challenge in characterizing CoT-supervised learning lies in the asymmetry between the training and testing objectives:

  • Training objective: CoT risk RDCoT(h):=Px,y,z∼D[(he2e(x),hCoT(x))≠(y,z)]\cotrisk{\calD}(h) := \probunder{x,y,z \sim \calD}{(\hete{h}(x), \hcot{h}(x)) \neq (y, z)}.
  • Test objective: End-to-end risk RDe2e(h):=Px,y∼Dx,y[he2e(x)≠y]\eterisk{\calD}(h) := \probunder{x,y \sim \calD_{x,y}}{\hete{h}(x) \neq y}.

This asymmetry prevents the direct application of classical learning theory results.

One approach to studying CoT-supervised learning, taken by recent related work5 A Theory of Learning with Autoregressive Chain of Thought Nirmit Joshi, Gal Vardi, et al.arXiv preprint · 2025 arXiv , sidesteps this asymmetry by bounding the CoT risk instead of the end-to-end risk, noting that RDCoT(h)≥RDe2e(h)\cotrisk{\calD}(h) \geq \eterisk{\calD}(h) for all hh. This problem is now symmetric because both the training and testing objectives are the CoT error, enabling a direct application of standard learning results. In particular, this approach yields a sample complexity of O(VC(LCoT(H))/ε)\bigO\big(\VC(\calLCoT(\calH)) / \epsilon\big), where LCoT(H):={ℓhCoT:(x,y,z)↦1{h(x)≠(y,z)}}\calLCoT(\calH) := \{\ell_h^{\CoT}: (x, y, z) \mapsto \Ind{h(x) \neq (y, z)}\}.

While this provides an upper bound, the resulting rate, scaling as 1/ε1/\epsilon, matches that of standard end-to-end supervision (in terms of the dependence on ε\epsilon). Yet, we know that CoT supervision can provide significant statistical advantages in practice. This suggests that the analysis is loose, failing to capture the full benefit of CoT supervision through the extra information encoded in the traces.

To quantify the true advantage of CoT supervision, we need a measure that explicitly links the two types of risk and captures the information gain per observed trace.

The Chain-of-Thought Information

To quantify the statistical advantage of intermediate supervision, we introduce the Chain-of-Thought Information, capturing the added discriminative power that CoT supervision provides over standard end-to-end learning.

Definition (CoT Information)

For a CoT hypothesis class H\calH and realizable distribution D\calD over X×Y×Z\calX \times \calY \times \calZ, the CoT information is defined as the function

IDCoT(ε;H):=inf⁡h∈ΔDe2e(ε;H){−log⁡Px,y,z∼D[(hCoT(x),he2e(x))=(z,y)]},\cotinfodomain{\calD}(\epsilon; \calH) := \inf_{h \in \Deltaete_{\calD}(\epsilon; \calH)} \Big\{- \log \probunder{x,y,z \sim \calD}{(\hcot{h}(x), \hete{h}(x)) = (z, y)}\Big\},

where ΔDe2e(ε;H):={h∈H:Px,y[he2e(x)≠y]>ε}\Deltaete_{\calD}(\epsilon; \calH) := \{h \in \calH : \probunder{x,y}{\hete{h}(x) \neq y} > \epsilon\} is the set of hypotheses that disagree with the end-to-end reference function on at least an ε\epsilon fraction of the inputs.

Conceptually, the CoT information quantifies how much more discriminative power is packed into each annotated example. When the CoT information is large, observing the CoT reveals additional information about the target hypothesis, enabling faster learning.

In the special case where reasoning traces provide no useful signal (for instance, if they are independent of the final output), the CoT information collapses to the standard ε\epsilon rate. Conversely, in the extreme case where the trace always uniquely identifies the target function, the CoT information becomes infinite—implying that a single example suffices to recover the target function.

Key Properties of the CoT Information:

  • IDCoT(ε;H)≥ε\cotinfodomain{\calD}(\epsilon; \calH) \geq \epsilon — CoT supervision is never less informative than end-to-end supervision.
  • Monotone increasing in ε\epsilon — smaller target error requires more information.
  • Monotone decreasing in H\calH — larger hypothesis classes are harder to learn.

We will see that the CoT information characterizes the sample complexity of learning under CoT supervision, improving the standard 1/ε1/\epsilon rate to a potentially much faster 1/IDCoT(ε;H)1/\cotinfodomain{\calD}(\epsilon; \calH). This reframes CoT supervision as a statistically stronger form of learning signal: one that not only corrects what the model predicts, but constrains how it reaches the answer.

Main Theorem: CoT Information Governs the Statistical Rate of Learning under CoT Supervision

Increasing sample size
Geometry of CoT information: consistency sets shrink much faster under CoT supervision.
Result (Sample Complexity Under CoT Supervision)

For finite H\calH, the CoT consistency rule

CoT-Cons⁡(S;H):={h∈H:he2e(xi)=yi,hCoT(xi)=zi, ∀i}\CoTCons(S; \calH) := \{h \in \calH : \hete{h}(x_i) = y_i, \hcot{h}(x_i) = z_i, \ \forall i\}

has sample complexity

m(ε,δ)=log⁡∣H∣+log⁡(1/δ)IDCoT(ε;H).m(\epsilon, \delta) = \frac{\log |\calH| + \log(1/\delta)}{\cotinfodomain{\calD}(\epsilon; \calH)}.

That is, whenever m≥m(ε,δ)m \geq m(\epsilon, \delta), we have that with probability at least 1−δ1 - \delta over S∼DmS \sim \calD^m,

∀h∈CoT-Cons⁡(S;H), RDe2e(h)≤ε.\forall h \in \CoTCons(S; \calH), \ \eterisk{\calD}(h) \leq \epsilon.

The take away: the 1/ε1/\epsilon rate of end-to-end learning is improved to the potentially much faster 1/IDCoT(ε;H)1/\cotinfodomain{\calD}(\epsilon; \calH) rate under CoT supervision. In particular, the ratio IDCoT(ε;H)/ε\cotinfodomain{\calD}(\epsilon; \calH) / \epsilon can be interpreted as the relative value of a single CoT-labeled example compared to an end-to-end labeled example.

For infinite classes, the result extends to

m(ε,δ)=O ⁣((1IDCoT(ε;H)+1)(VC(LCoT(H))⋅log⁡(1IDCoT(ε;H)+1)+log⁡(1/δ))).m(\epsilon, \delta) = \bigO\!\left(\Big(\frac{1}{\cotinfodomain{\calD}(\epsilon; \calH)} + 1\Big)\Big(\VC(\calLCoT(\calH)) \cdot \log \big(\tfrac{1}{\cotinfodomain{\calD}(\epsilon; \calH)} + 1\big) + \log(1/\delta)\Big)\right).

Here, the VC dimension of the CoT loss class LCoT(H)\mathcal{L}_{\text{CoT}}(\mathcal{H}) replaces the log-cardinality term, but the dependence on IDCoT(ε;H)\cotinfodomain{\mathcal{D}}(\epsilon; \mathcal{H}) remains the key driver of the rate.

Preview of the Agnostic Setting

The guarantees above hold in the realizable case, where both outputs and reasoning traces can be represented within the hypothesis class. In practice, however, this assumption may not hold. Chain-of-thought traces are often noisy, incomplete, or stylistically inconsistent with the model’s representational structure, creating a potential mismatch between the supervision signal and the learner’s capacity.

The message becomes somewhat more complex in the agnostic setting. In particular, in general, CoT supervision can even be detrimental in the agnostic setting. Consider the following pathological example, where the distribution D\calD has realizable outputs but unrealizable CoTs: inf⁡h∈HRDe2e(h)=0\inf_{h \in \calH} \eterisk{\calD}(h) = 0 yet inf⁡h∈HRDCoT(h)=1\inf_{h \in \calH} \cotrisk{\calD}(h) = 1. In this case, the CoT consistency rule yields CoT-ERM⁡(S;H)=H\CoTERM(S; \calH) = \calH (no guarantees), whereas standard end-to-end learning still succeeds with O(VC(Le2e(H))/ε)\bigO\big(\VC(\calLete(\calH)) / \epsilon\big) samples.

To extend our analysis to the agnostic setting, we introduce an agnostic variant of the CoT information that links the excess CoT risk to the excess end-to-end risk. This agnostic CoT information measures the alignment between observed traces and the hypothesis class, capturing how well the CoT supervision can guide learning even when perfect trace reconstruction is impossible. We refer the reader to the full paper for details.

Part IV: Information-Theoretic Lower Bounds

The upper bounds established above show that CoT information governs the sample complexity of learning under CoT supervision. But are these rates tight? Do they capture the right complexity measure?

In the following, we establish information-theoretic lower bounds that validate CoT information as the fundamental quantity governing learning with CoT supervision. Such results show that a certain number of samples, scaling inversely with the CoT information, are necessary for any learning algorithm to succeed.

Lower Bound via Two-Point Method

Result (Lower Bound via Two-Point Method)

Fix a distribution D\calD over X\calX, and draw mm samples, x1,…,xm∼i.i.d.Dx_1, \ldots, x_m \simiid \calD. If

m<log⁡(1/δ)/ID,h⋆CoT(ε;H),m < \log(1/\delta) / \cotinfo(\epsilon; \calH),

then with probability ≥δ\geq \delta there exists an hh with end-to-end error ≥ε\geq \epsilon which is indistinguishable from h⋆\hstar on the sample. Moreover, for any learning algorithm A\calA, we have

sup⁡h⋆∈HES∼Ph⋆⊗[RDe2e(A(S))]≥12sup⁡h⋆,εε⋅exp⁡(−m⋅ID,h⋆CoT(ε;H)).\sup_{\hstar \in \calH} \expectunder{S \sim P_{\hstar}^{\otimes}}{\eterisk{\calD}(\calA(S))} \geq \tfrac{1}{2} \sup_{\hstar, \epsilon} \epsilon \cdot \exp(-m \cdot \cotinfo(\epsilon; \calH)).

This lower bound exhibits the expected dependence on the error parameter ε\epsilon through the CoT information, confirming its role as the governing quantity for learning with CoT supervision.

However, it does not scale with size of the hypothesis class. This is a limitation of the two-point method, which only considers a pair of hypotheses. To capture class size, we turn to a more sophisticated packing-based argument employing information-theoretic tools.

Lower Bound via Fano’s Method

Fano’s method generalizes the two-point argument by considering a packing of many hypotheses that are pairwise well-separated with respect to end-to-end error

Result (Lower Bound via Fano's Method)

Fix a distribution D\calD over X\calX, and draw mm samples, x1,…,xm∼i.i.d.Dx_1, \ldots, x_m \simiid \calD. For any algorithm A\calA, if the number of samples satisfies

m≤log⁡M(H;dDe2e,ε)2(CQ⋅sup⁡πEh1,h2∼π[IDCoT(h1,h2)]+log⁡2),m \le \frac{\log M(\mathcal{H}; d_{\mathcal{D}}^{\text{e2e}}, \epsilon)}{2 \big(C_Q \cdot \sup_{\pi} \mathbb{E}_{h_1, h_2 \sim \pi}[\relcotinfo(h_1, h_2)] + \log 2\big)},

then the end-to-end error must be large for some h⋆\hstar:

sup⁡h⋆∈HPr⁡[RD,h⋆e2e(A(S))≥ε/2]≥1/2.\sup_{\hstar \in \calH} \Pr[\eterisk{\mathcal{D}, \hstar}(\mathcal{A}(S)) \ge \epsilon / 2] \ge 1/2.

Here, M(H;dDe2e,ε)M(\mathcal{H}; d_{\mathcal{D}}^{\text{e2e}}, \epsilon) denotes the packing number of the hypothesis class under the end-to-end metric, and IDCoT(h1,h2)\relcotinfo(h_1, h_2) is the pairwise CoT information, quantifying how distinguishable two hypotheses are when reasoning traces are observed.

This result scales also with the size of the hypothesis class, through its packing number. Together with the two-point bound, it suggests that the CoT information is not merely an artifact of the upper-bound analysis, but a fundamental measure of the statistical complexity of learning under CoT supervision.

Part V: Empirical Evaluation via Simulations

The theoretical framework suggests that the CoT information IDCoT(ε;H)\cotinfodomain{\mathcal{D}}(\epsilon; \mathcal{H}) should govern how much faster learning occurs under CoT supervision. To test this prediction, we perform controlled simulations where all quantities can be computed exactly, comparing empirical sample complexity under standard end-to-end supervision versus CoT-augmented training.

Example 1: Linear Autoregressive Model

Our first experiment studies a simplified autoregressive generation process over a binary alphabet Σ={0,1}\Sigma = \{0, 1\}. Each model has window size d=8d = 8, produces T=16T = 16 autoregressive steps, and uses weights w∈{−1,0,+1}dw \in \{-1, 0, +1\}^d. The CoT trace corresponds to the full sequence of intermediate tokens, while the final output yy is the last generated token.

012345
0.00.20.40.60.81.0
ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.000 ℐᶜᵒᵀ(h₁, h₂) = -0.000ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.055 ℐᶜᵒᵀ(h₁, h₂) = 0.319ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.070 ℐᶜᵒᵀ(h₁, h₂) = 0.445ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.070 ℐᶜᵒᵀ(h₁, h₂) = 0.678ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.078 ℐᶜᵒᵀ(h₁, h₂) = 0.482ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.086 ℐᶜᵒᵀ(h₁, h₂) = 0.421ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.086 ℐᶜᵒᵀ(h₁, h₂) = 1.023ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.094 ℐᶜᵒᵀ(h₁, h₂) = 0.758ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.094 ℐᶜᵒᵀ(h₁, h₂) = 1.268ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.102 ℐᶜᵒᵀ(h₁, h₂) = 0.709ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.102 ℐᶜᵒᵀ(h₁, h₂) = 0.725ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.102 ℐᶜᵒᵀ(h₁, h₂) = 1.163ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.133 ℐᶜᵒᵀ(h₁, h₂) = 1.068ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.133 ℐᶜᵒᵀ(h₁, h₂) = 1.451ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.133 ℐᶜᵒᵀ(h₁, h₂) = 1.856ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.133 ℐᶜᵒᵀ(h₁, h₂) = 2.773ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.141 ℐᶜᵒᵀ(h₁, h₂) = 0.845ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.148 ℐᶜᵒᵀ(h₁, h₂) = 0.940ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.156 ℐᶜᵒᵀ(h₁, h₂) = 1.091ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.156 ℐᶜᵒᵀ(h₁, h₂) = 2.287ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.164 ℐᶜᵒᵀ(h₁, h₂) = 1.418ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.164 ℐᶜᵒᵀ(h₁, h₂) = 1.716ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.172 ℐᶜᵒᵀ(h₁, h₂) = 1.716ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.172 ℐᶜᵒᵀ(h₁, h₂) = 1.908ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.180 ℐᶜᵒᵀ(h₁, h₂) = 2.019ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.180 ℐᶜᵒᵀ(h₁, h₂) = 2.367ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.195 ℐᶜᵒᵀ(h₁, h₂) = 0.827ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.195 ℐᶜᵒᵀ(h₁, h₂) = 1.451ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.195 ℐᶜᵒᵀ(h₁, h₂) = 2.549ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.203 ℐᶜᵒᵀ(h₁, h₂) = 1.297ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.203 ℐᶜᵒᵀ(h₁, h₂) = 1.355ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.203 ℐᶜᵒᵀ(h₁, h₂) = 2.454ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.207 ℐᶜᵒᵀ(h₁, h₂) = 3.348ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.211 ℐᶜᵒᵀ(h₁, h₂) = 1.188ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.219 ℐᶜᵒᵀ(h₁, h₂) = 1.355ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.219 ℐᶜᵒᵀ(h₁, h₂) = 1.761ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.219 ℐᶜᵒᵀ(h₁, h₂) = 3.348ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.227 ℐᶜᵒᵀ(h₁, h₂) = 1.594ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.234 ℐᶜᵒᵀ(h₁, h₂) = 1.326ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.238 ℐᶜᵒᵀ(h₁, h₂) = 3.599ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.238 ℐᶜᵒᵀ(h₁, h₂) = 3.753ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.238 ℐᶜᵒᵀ(h₁, h₂) = 3.936ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.242 ℐᶜᵒᵀ(h₁, h₂) = 1.962ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.258 ℐᶜᵒᵀ(h₁, h₂) = 1.761ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.258 ℐᶜᵒᵀ(h₁, h₂) = 3.936ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.262 ℐᶜᵒᵀ(h₁, h₂) = 2.906ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.262 ℐᶜᵒᵀ(h₁, h₂) = 3.936ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.266 ℐᶜᵒᵀ(h₁, h₂) = 2.079ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.273 ℐᶜᵒᵀ(h₁, h₂) = 2.367ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.285 ℐᶜᵒᵀ(h₁, h₂) = 3.243ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.285 ℐᶜᵒᵀ(h₁, h₂) = 3.753ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.289 ℐᶜᵒᵀ(h₁, h₂) = 2.144ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.289 ℐᶜᵒᵀ(h₁, h₂) = 2.837ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.293 ℐᶜᵒᵀ(h₁, h₂) = 2.712ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.293 ℐᶜᵒᵀ(h₁, h₂) = 2.773ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.301 ℐᶜᵒᵀ(h₁, h₂) = 4.159ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.305 ℐᶜᵒᵀ(h₁, h₂) = 2.019ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.313 ℐᶜᵒᵀ(h₁, h₂) = 3.147ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.328 ℐᶜᵒᵀ(h₁, h₂) = 3.936ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.328 ℐᶜᵒᵀ(h₁, h₂) = 3.936ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.328 ℐᶜᵒᵀ(h₁, h₂) = 4.159ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.332 ℐᶜᵒᵀ(h₁, h₂) = 3.348ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.332 ℐᶜᵒᵀ(h₁, h₂) = 4.852ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.336 ℐᶜᵒᵀ(h₁, h₂) = 2.287ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.336 ℐᶜᵒᵀ(h₁, h₂) = 4.852ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.340 ℐᶜᵒᵀ(h₁, h₂) = 4.159ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.344 ℐᶜᵒᵀ(h₁, h₂) = 3.753ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.348 ℐᶜᵒᵀ(h₁, h₂) = 4.159ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.359 ℐᶜᵒᵀ(h₁, h₂) = 2.549ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.359 ℐᶜᵒᵀ(h₁, h₂) = 3.466ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.367 ℐᶜᵒᵀ(h₁, h₂) = 3.060ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.375 ℐᶜᵒᵀ(h₁, h₂) = 2.980ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.383 ℐᶜᵒᵀ(h₁, h₂) = 1.761ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.391 ℐᶜᵒᵀ(h₁, h₂) = 3.060ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.395 ℐᶜᵒᵀ(h₁, h₂) = 3.466ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.410 ℐᶜᵒᵀ(h₁, h₂) = 2.049ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.414 ℐᶜᵒᵀ(h₁, h₂) = 3.348ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.426 ℐᶜᵒᵀ(h₁, h₂) = 2.178ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.426 ℐᶜᵒᵀ(h₁, h₂) = 3.348ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.430 ℐᶜᵒᵀ(h₁, h₂) = 2.655ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.430 ℐᶜᵒᵀ(h₁, h₂) = 4.447ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.434 ℐᶜᵒᵀ(h₁, h₂) = 2.367ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.434 ℐᶜᵒᵀ(h₁, h₂) = 3.243ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.438 ℐᶜᵒᵀ(h₁, h₂) = 1.451ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.445 ℐᶜᵒᵀ(h₁, h₂) = 3.936ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.449 ℐᶜᵒᵀ(h₁, h₂) = 3.147ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.453 ℐᶜᵒᵀ(h₁, h₂) = 4.447ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.457 ℐᶜᵒᵀ(h₁, h₂) = 4.447ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.461 ℐᶜᵒᵀ(h₁, h₂) = 3.348ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.492 ℐᶜᵒᵀ(h₁, h₂) = 3.936ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.508 ℐᶜᵒᵀ(h₁, h₂) = 4.447ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.512 ℐᶜᵒᵀ(h₁, h₂) = 4.159ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.516 ℐᶜᵒᵀ(h₁, h₂) = 3.936ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.523 ℐᶜᵒᵀ(h₁, h₂) = 1.908ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.523 ℐᶜᵒᵀ(h₁, h₂) = 2.367ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.527 ℐᶜᵒᵀ(h₁, h₂) = 3.753ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.531 ℐᶜᵒᵀ(h₁, h₂) = 1.856ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.547 ℐᶜᵒᵀ(h₁, h₂) = 2.019ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.547 ℐᶜᵒᵀ(h₁, h₂) = 3.599ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.563 ℐᶜᵒᵀ(h₁, h₂) = 4.159ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.566 ℐᶜᵒᵀ(h₁, h₂) = 3.466ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.570 ℐᶜᵒᵀ(h₁, h₂) = 4.159ℙ(h₁ᵉ²ᵉ(x) ≠ h₂ᵉ²ᵉ(x)) = 0.590 ℐᶜᵒᵀ(h₁, h₂) = 3.147
Relative CoT information between pairs of hypotheses versus their end-to-end disagreement. Observing the CoT makes distinguishing hypotheses statistically easier.
0123
10⁰10⁻¹10⁻²
ε = 0.0547ε = 0.00732 ℐᶜᵒᵀ = 0.319ε = 0.0101 ℐᶜᵒᵀ = 0.319ε = 0.0202 ℐᶜᵒᵀ = 0.319ε = 0.0303 ℐᶜᵒᵀ = 0.319ε = 0.0404 ℐᶜᵒᵀ = 0.319ε = 0.0505 ℐᶜᵒᵀ = 0.319ε = 0.0606 ℐᶜᵒᵀ = 0.421ε = 0.0707 ℐᶜᵒᵀ = 0.421ε = 0.0808 ℐᶜᵒᵀ = 0.421ε = 0.0909 ℐᶜᵒᵀ = 0.709ε = 0.101 ℐᶜᵒᵀ = 0.709ε = 0.111 ℐᶜᵒᵀ = 0.827ε = 0.121 ℐᶜᵒᵀ = 0.827ε = 0.131 ℐᶜᵒᵀ = 0.827ε = 0.141 ℐᶜᵒᵀ = 0.827ε = 0.152 ℐᶜᵒᵀ = 0.827ε = 0.162 ℐᶜᵒᵀ = 0.827ε = 0.172 ℐᶜᵒᵀ = 0.827ε = 0.182 ℐᶜᵒᵀ = 0.827ε = 0.192 ℐᶜᵒᵀ = 0.827ε = 0.202 ℐᶜᵒᵀ = 1.188ε = 0.212 ℐᶜᵒᵀ = 1.326ε = 0.222 ℐᶜᵒᵀ = 1.326ε = 0.232 ℐᶜᵒᵀ = 1.326ε = 0.242 ℐᶜᵒᵀ = 1.451ε = 0.253 ℐᶜᵒᵀ = 1.451ε = 0.263 ℐᶜᵒᵀ = 1.451ε = 0.273 ℐᶜᵒᵀ = 1.451ε = 0.283 ℐᶜᵒᵀ = 1.451ε = 0.293 ℐᶜᵒᵀ = 1.451ε = 0.303 ℐᶜᵒᵀ = 1.451ε = 0.313 ℐᶜᵒᵀ = 1.451ε = 0.323 ℐᶜᵒᵀ = 1.451ε = 0.333 ℐᶜᵒᵀ = 1.451ε = 0.343 ℐᶜᵒᵀ = 1.451ε = 0.354 ℐᶜᵒᵀ = 1.451ε = 0.364 ℐᶜᵒᵀ = 1.451ε = 0.374 ℐᶜᵒᵀ = 1.451ε = 0.384 ℐᶜᵒᵀ = 1.451ε = 0.394 ℐᶜᵒᵀ = 1.451ε = 0.404 ℐᶜᵒᵀ = 1.451ε = 0.414 ℐᶜᵒᵀ = 1.451ε = 0.424 ℐᶜᵒᵀ = 1.451ε = 0.434 ℐᶜᵒᵀ = 1.451ε = 0.444 ℐᶜᵒᵀ = 1.856ε = 0.455 ℐᶜᵒᵀ = 1.856ε = 0.465 ℐᶜᵒᵀ = 1.856ε = 0.475 ℐᶜᵒᵀ = 1.856ε = 0.485 ℐᶜᵒᵀ = 1.856ε = 0.495 ℐᶜᵒᵀ = 1.856ε = 0.505 ℐᶜᵒᵀ = 1.856ε = 0.515 ℐᶜᵒᵀ = 1.856ε = 0.525 ℐᶜᵒᵀ = 1.856ε = 0.535 ℐᶜᵒᵀ = 2.019ε = 0.546 ℐᶜᵒᵀ = 2.019ε = 0.556 ℐᶜᵒᵀ = 3.147ε = 0.566 ℐᶜᵒᵀ = 3.147ε = 0.576 ℐᶜᵒᵀ = 3.147ε = 0.586 ℐᶜᵒᵀ = 3.147
The CoT information function IDCoT(ε;H)\cotinfodomain{\mathcal{D}}(\epsilon; \mathcal{H}). The dashed line is the line y=εy = \epsilon. The CoT information always dominates the ε\epsilon baseline.
020406080100Empirical sample complexity10⁰10⁻¹10⁻²10⁻³
CoT-Cons, E2E errorE2E-Cons, E2E errorCoT-Cons, CoT errorE2E-Cons, CoT error
Empirical sample complexity for end-to-end versus CoT learning.
0.00.20.40.60.81.0
10⁰10¹10²
Sample size
CoT-Cons, m = 1 0.186 (0.152–0.218)CoT-Cons, m = 2 0.396 (0.354–0.440)CoT-Cons, m = 3 0.562 (0.520–0.604)CoT-Cons, m = 4 0.682 (0.640–0.724)CoT-Cons, m = 5 0.754 (0.714–0.792)CoT-Cons, m = 6 0.840 (0.806–0.870)CoT-Cons, m = 7 0.890 (0.862–0.916)CoT-Cons, m = 8 0.938 (0.916–0.958)CoT-Cons, m = 9 0.956 (0.938–0.972)CoT-Cons, m = 10 0.970 (0.954–0.984)CoT-Cons, m = 15 0.996 (0.990–1.000)CoT-Cons, m = 20 1.000 (1.000–1.000)CoT-Cons, m = 25 1.000 (1.000–1.000)CoT-Cons, m = 35 1.000 (1.000–1.000)CoT-Cons, m = 50 1.000 (1.000–1.000)CoT-Cons, m = 100 1.000 (1.000–1.000)E2E-Cons, m = 1 0.002 (0.000–0.006)E2E-Cons, m = 2 0.000 (0.000–0.000)E2E-Cons, m = 3 0.000 (0.000–0.000)E2E-Cons, m = 4 0.004 (0.000–0.010)E2E-Cons, m = 5 0.000 (0.000–0.000)E2E-Cons, m = 6 0.004 (0.000–0.010)E2E-Cons, m = 7 0.014 (0.006–0.026)E2E-Cons, m = 8 0.018 (0.008–0.032)E2E-Cons, m = 9 0.032 (0.018–0.048)E2E-Cons, m = 10 0.066 (0.046–0.088)E2E-Cons, m = 15 0.224 (0.190–0.262)E2E-Cons, m = 20 0.358 (0.318–0.398)E2E-Cons, m = 25 0.526 (0.484–0.568)E2E-Cons, m = 35 0.718 (0.676–0.758)E2E-Cons, m = 50 0.886 (0.858–0.912)E2E-Cons, m = 100 0.998 (0.994–1.000)
Probability that each learning rule achieves zero error as the sample size grows.

The empirical data closely match the theoretical prediction: lim⁡ε→0IDCoT(ε;H)/ε+≈6\lim_{\epsilon \to 0} \cotinfodomain{\mathcal{D}}(\epsilon; \mathcal{H}) / \epsilon^+ \approx 6, corresponding to a roughly 6× theoretical gain. Measured sample complexity shows an actual ≈5× empirical improvement, validating that CoT information accurately predicts the observed acceleration in learning.

Example 2: Learning Regular Languages

Our second experiment examines multi-step reasoning via regular language recognition. Here, he2e(x)h^{\text{e2e}}(x) indicates whether a string xx belongs to a regular language L\mathcal{L}, while hCoT(x)h^{\text{CoT}}(x) records the sequence of states traversed by the corresponding deterministic finite automaton during recognition. The CoT thus captures the latent computational process underlying membership decisions.

00101110start0123
DFA whose state trajectory forms the chain-of-thought trace.
0200400600
10⁰10⁻¹10⁻²10⁻³
CoT detail level 1CoT detail level 2CoT detail level 3CoT detail level 4CoT detail level 5CoT detail level 6CoT detail level 7CoT detail level 8CoT detail level 9CoT detail level 10CoT detail level 1 ε = 0.00100: 1.0CoT detail level 1 ε = 0.00194: 1.0CoT detail level 1 ε = 0.00196: 2.0CoT detail level 1 ε = 0.00390: 1.0CoT detail level 1 ε = 0.00393: 7.6CoT detail level 1 ε = 0.00591: 5.0CoT detail level 1 ε = 0.00986: 3.0CoT detail level 1 ε = 0.0194: 1.5CoT detail level 1 ε = 0.0342: 1.2CoT detail level 1 ε = 0.0604: 1.0CoT detail level 1 ε = 0.0647: 1.1CoT detail level 1 ε = 0.111: 1.1CoT detail level 1 ε = 0.116: 1.1CoT detail level 1 ε = 0.189: 1.1CoT detail level 1 ε = 0.237: 1.2CoT detail level 1 ε = 0.357: 1.2CoT detail level 1 ε = 0.933: 2.9CoT detail level 1 ε = 0.940: 3.7CoT detail level 1 ε = 0.966: 3.6CoT detail level 1 ε = 0.973: 5.7CoT detail level 1 ε = 0.993: 5.6CoT detail level 2 ε = 0.00100: 184.6CoT detail level 2 ε = 0.00196: 184.4CoT detail level 2 ε = 0.00217: 166.2CoT detail level 2 ε = 0.00241: 149.8CoT detail level 2 ε = 0.00269: 134.2CoT detail level 2 ε = 0.00300: 120.1CoT detail level 2 ε = 0.00338: 106.8CoT detail level 2 ε = 0.00380: 94.9CoT detail level 2 ε = 0.00430: 83.8CoT detail level 2 ε = 0.00491: 73.5CoT detail level 2 ε = 0.00563: 64.0CoT detail level 2 ε = 0.00651: 55.4CoT detail level 2 ε = 0.00758: 47.5CoT detail level 2 ε = 0.00895: 40.3CoT detail level 2 ε = 0.0106: 33.9CoT detail level 2 ε = 0.0129: 27.9CoT detail level 2 ε = 0.0159: 22.7CoT detail level 2 ε = 0.0201: 17.9CoT detail level 2 ε = 0.0261: 13.8CoT detail level 2 ε = 0.0352: 10.3CoT detail level 2 ε = 0.0501: 7.2CoT detail level 2 ε = 0.0723: 5.0CoT detail level 2 ε = 0.0738: 5.1CoT detail level 2 ε = 0.111: 3.5CoT detail level 2 ε = 0.113: 3.7CoT detail level 2 ε = 0.168: 2.8CoT detail level 2 ε = 0.170: 3.1CoT detail level 2 ε = 0.249: 2.3CoT detail level 2 ε = 0.256: 2.4CoT detail level 2 ε = 0.390: 1.9CoT detail level 2 ε = 0.399: 2.1CoT detail level 2 ε = 0.497: 2.0CoT detail level 2 ε = 0.501: 2.8CoT detail level 2 ε = 0.608: 2.7CoT detail level 2 ε = 0.638: 2.7CoT detail level 2 ε = 0.753: 2.8CoT detail level 2 ε = 0.796: 3.0CoT detail level 2 ε = 0.835: 3.1CoT detail level 2 ε = 0.853: 3.8CoT detail level 2 ε = 0.933: 3.7CoT detail level 2 ε = 0.940: 4.4CoT detail level 2 ε = 0.966: 4.3CoT detail level 2 ε = 0.973: 5.7CoT detail level 2 ε = 0.993: 5.6CoT detail level 3 ε = 0.00100: 278.8CoT detail level 3 ε = 0.00196: 278.5CoT detail level 3 ε = 0.00215: 252.8CoT detail level 3 ε = 0.00237: 229.5CoT detail level 3 ε = 0.00263: 206.8CoT detail level 3 ε = 0.00292: 186.5CoT detail level 3 ε = 0.00324: 168.1CoT detail level 3 ε = 0.00359: 151.5CoT detail level 3 ε = 0.00401: 135.7CoT detail level 3 ε = 0.00448: 121.5CoT detail level 3 ε = 0.00504: 108.0CoT detail level 3 ε = 0.00567: 96.0CoT detail level 3 ε = 0.00642: 84.8CoT detail level 3 ε = 0.00733: 74.3CoT detail level 3 ε = 0.00835: 65.2CoT detail level 3 ε = 0.00966: 56.4CoT detail level 3 ε = 0.0112: 48.4CoT detail level 3 ε = 0.0132: 41.3CoT detail level 3 ε = 0.0157: 34.8CoT detail level 3 ε = 0.0189: 28.8CoT detail level 3 ε = 0.0232: 23.4CoT detail level 3 ε = 0.0292: 18.6CoT detail level 3 ε = 0.0377: 14.4CoT detail level 3 ε = 0.0504: 10.8CoT detail level 3 ε = 0.0708: 7.7CoT detail level 3 ε = 0.0835: 6.7CoT detail level 3 ε = 0.0847: 6.9CoT detail level 3 ε = 0.122: 4.9CoT detail level 3 ε = 0.168: 3.9CoT detail level 3 ε = 0.170: 4.2CoT detail level 3 ε = 0.249: 3.0CoT detail level 3 ε = 0.256: 3.1CoT detail level 3 ε = 0.390: 2.2CoT detail level 3 ε = 0.399: 2.4CoT detail level 3 ε = 0.497: 2.3CoT detail level 3 ε = 0.501: 3.4CoT detail level 3 ε = 0.571: 3.2CoT detail level 3 ε = 0.579: 3.6CoT detail level 3 ε = 0.679: 3.1CoT detail level 3 ε = 0.688: 3.7CoT detail level 3 ε = 0.796: 3.6CoT detail level 3 ε = 0.818: 3.6CoT detail level 3 ε = 0.853: 3.9CoT detail level 3 ε = 0.933: 3.7CoT detail level 3 ε = 0.940: 4.4CoT detail level 3 ε = 0.966: 4.3CoT detail level 3 ε = 0.973: 5.7CoT detail level 3 ε = 0.993: 5.6CoT detail level 4 ε = 0.00100: 394.4CoT detail level 4 ε = 0.00196: 393.9CoT detail level 4 ε = 0.00215: 357.5CoT detail level 4 ε = 0.00237: 324.5CoT detail level 4 ε = 0.00261: 294.6CoT detail level 4 ε = 0.00288: 267.4CoT detail level 4 ε = 0.00317: 242.7CoT detail level 4 ε = 0.00352: 218.8CoT detail level 4 ε = 0.00390: 197.3CoT detail level 4 ε = 0.00433: 177.8CoT detail level 4 ε = 0.00481: 160.3CoT detail level 4 ε = 0.00533: 144.5CoT detail level 4 ε = 0.00595: 129.4CoT detail level 4 ε = 0.00665: 115.8CoT detail level 4 ε = 0.00748: 103.0CoT detail level 4 ε = 0.00841: 91.6CoT detail level 4 ε = 0.00953: 80.8CoT detail level 4 ε = 0.0109: 70.9CoT detail level 4 ε = 0.0125: 61.7CoT detail level 4 ε = 0.0144: 53.4CoT detail level 4 ε = 0.0168: 45.9CoT detail level 4 ε = 0.0198: 38.9CoT detail level 4 ε = 0.0237: 32.5CoT detail level 4 ε = 0.0288: 26.8CoT detail level 4 ε = 0.0357: 21.6CoT detail level 4 ε = 0.0452: 17.1CoT detail level 4 ε = 0.0591: 13.0CoT detail level 4 ε = 0.0780: 10.0CoT detail level 4 ε = 0.108: 7.3CoT detail level 4 ε = 0.125: 6.6CoT detail level 4 ε = 0.128: 6.6CoT detail level 4 ε = 0.168: 5.2CoT detail level 4 ε = 0.170: 5.5CoT detail level 4 ε = 0.258: 3.8CoT detail level 4 ε = 0.390: 2.6CoT detail level 4 ε = 0.396: 2.9CoT detail level 4 ε = 0.497: 2.7CoT detail level 4 ε = 0.501: 4.2CoT detail level 4 ε = 0.522: 4.1CoT detail level 4 ε = 0.608: 3.9CoT detail level 4 ε = 0.621: 4.0CoT detail level 4 ε = 0.679: 3.7CoT detail level 4 ε = 0.684: 4.7CoT detail level 4 ε = 0.790: 4.6CoT detail level 4 ε = 0.847: 4.5CoT detail level 4 ε = 0.859: 4.8CoT detail level 4 ε = 0.933: 4.5CoT detail level 4 ε = 0.940: 5.2CoT detail level 4 ε = 0.966: 5.0CoT detail level 4 ε = 0.973: 5.7CoT detail level 4 ε = 0.993: 5.6CoT detail level 5 ε = 0.00100: 478.7CoT detail level 5 ε = 0.00194: 478.7CoT detail level 5 ε = 0.00196: 478.1CoT detail level 5 ε = 0.00215: 434.0CoT detail level 5 ε = 0.00237: 394.0CoT detail level 5 ε = 0.00261: 357.6CoT detail level 5 ε = 0.00288: 324.6CoT detail level 5 ε = 0.00317: 294.7CoT detail level 5 ε = 0.00350: 267.5CoT detail level 5 ε = 0.00385: 242.8CoT detail level 5 ε = 0.00427: 218.9CoT detail level 5 ε = 0.00474: 197.3CoT detail level 5 ε = 0.00526: 177.9CoT detail level 5 ε = 0.00583: 160.3CoT detail level 5 ε = 0.00647: 144.6CoT detail level 5 ε = 0.00723: 129.4CoT detail level 5 ε = 0.00807: 115.9CoT detail level 5 ε = 0.00908: 103.0CoT detail level 5 ε = 0.0102: 91.6CoT detail level 5 ε = 0.0116: 80.9CoT detail level 5 ε = 0.0132: 70.9CoT detail level 5 ε = 0.0151: 61.8CoT detail level 5 ε = 0.0175: 53.4CoT detail level 5 ε = 0.0204: 45.9CoT detail level 5 ε = 0.0241: 38.9CoT detail level 5 ε = 0.0288: 32.5CoT detail level 5 ε = 0.0331: 28.3CoT detail level 5 ε = 0.0335: 28.2CoT detail level 5 ε = 0.0413: 22.9CoT detail level 5 ε = 0.0497: 19.2CoT detail level 5 ε = 0.0616: 15.7CoT detail level 5 ε = 0.0785: 12.4CoT detail level 5 ε = 0.103: 9.5CoT detail level 5 ε = 0.104: 9.8CoT detail level 5 ε = 0.149: 6.8CoT detail level 5 ε = 0.231: 4.4CoT detail level 5 ε = 0.340: 3.0CoT detail level 5 ε = 0.345: 3.4CoT detail level 5 ε = 0.433: 3.0CoT detail level 5 ε = 0.439: 3.5CoT detail level 5 ε = 0.497: 3.1CoT detail level 5 ε = 0.501: 5.4CoT detail level 5 ε = 0.647: 4.5CoT detail level 5 ε = 0.679: 4.3CoT detail level 5 ε = 0.684: 5.4CoT detail level 5 ε = 0.818: 4.9CoT detail level 5 ε = 0.841: 5.0CoT detail level 5 ε = 0.933: 4.5CoT detail level 5 ε = 0.940: 5.2CoT detail level 5 ε = 0.966: 5.0CoT detail level 5 ε = 0.973: 5.7CoT detail level 5 ε = 0.993: 5.6CoT detail level 6 ε = 0.00100: 521.2CoT detail level 6 ε = 0.00194: 521.2CoT detail level 6 ε = 0.00196: 520.5CoT detail level 6 ε = 0.00215: 472.5CoT detail level 6 ε = 0.00237: 428.9CoT detail level 6 ε = 0.00261: 389.3CoT detail level 6 ε = 0.00288: 353.4CoT detail level 6 ε = 0.00317: 320.8CoT detail level 6 ε = 0.00350: 291.2CoT detail level 6 ε = 0.00385: 264.3CoT detail level 6 ε = 0.00424: 239.9CoT detail level 6 ε = 0.00471: 216.3CoT detail level 6 ε = 0.00522: 195.0CoT detail level 6 ε = 0.00579: 175.8CoT detail level 6 ε = 0.00642: 158.5CoT detail level 6 ε = 0.00718: 141.9CoT detail level 6 ε = 0.00801: 127.0CoT detail level 6 ε = 0.00895: 113.7CoT detail level 6 ε = 0.0101: 101.1CoT detail level 6 ε = 0.0113: 89.9CoT detail level 6 ε = 0.0128: 79.4CoT detail level 6 ε = 0.0146: 69.6CoT detail level 6 ε = 0.0168: 60.6CoT detail level 6 ε = 0.0194: 52.4CoT detail level 6 ε = 0.0228: 44.7CoT detail level 6 ε = 0.0269: 37.9CoT detail level 6 ε = 0.0322: 31.6CoT detail level 6 ε = 0.0390: 26.1CoT detail level 6 ε = 0.0484: 21.1CoT detail level 6 ε = 0.0552: 18.9CoT detail level 6 ε = 0.0713: 14.6CoT detail level 6 ε = 0.0953: 10.9CoT detail level 6 ε = 0.126: 8.5CoT detail level 6 ε = 0.185: 5.8CoT detail level 6 ε = 0.298: 3.6CoT detail level 6 ε = 0.340: 3.1CoT detail level 6 ε = 0.342: 3.8CoT detail level 6 ε = 0.433: 3.4CoT detail level 6 ε = 0.439: 3.8CoT detail level 6 ε = 0.497: 3.4CoT detail level 6 ε = 0.501: 5.8CoT detail level 6 ε = 0.608: 5.0CoT detail level 6 ε = 0.621: 5.2CoT detail level 6 ε = 0.679: 4.7CoT detail level 6 ε = 0.684: 6.3CoT detail level 6 ε = 0.830: 5.6CoT detail level 6 ε = 0.847: 5.7CoT detail level 6 ε = 0.933: 5.2CoT detail level 6 ε = 0.940: 5.9CoT detail level 6 ε = 0.993: 5.6CoT detail level 7 ε = 0.00100: 567.5CoT detail level 7 ε = 0.00194: 567.5CoT detail level 7 ε = 0.00196: 566.8CoT detail level 7 ε = 0.00215: 514.5CoT detail level 7 ε = 0.00237: 467.0CoT detail level 7 ε = 0.00261: 423.9CoT detail level 7 ε = 0.00288: 384.8CoT detail level 7 ε = 0.00317: 349.3CoT detail level 7 ε = 0.00350: 317.1CoT detail level 7 ε = 0.00385: 287.8CoT detail level 7 ε = 0.00424: 261.3CoT detail level 7 ε = 0.00467: 237.2CoT detail level 7 ε = 0.00518: 213.8CoT detail level 7 ε = 0.00575: 192.7CoT detail level 7 ε = 0.00638: 173.8CoT detail level 7 ε = 0.00708: 156.6CoT detail level 7 ε = 0.00790: 140.2CoT detail level 7 ε = 0.00883: 125.5CoT detail level 7 ε = 0.00986: 112.4CoT detail level 7 ε = 0.0111: 99.9CoT detail level 7 ε = 0.0126: 88.2CoT detail level 7 ε = 0.0142: 77.9CoT detail level 7 ε = 0.0162: 68.3CoT detail level 7 ε = 0.0186: 59.5CoT detail level 7 ε = 0.0215: 51.5CoT detail level 7 ε = 0.0253: 43.9CoT detail level 7 ε = 0.0298: 37.2CoT detail level 7 ε = 0.0357: 31.1CoT detail level 7 ε = 0.0436: 25.4CoT detail level 7 ε = 0.0544: 20.4CoT detail level 7 ε = 0.0693: 16.0CoT detail level 7 ε = 0.0914: 12.1CoT detail level 7 ε = 0.126: 8.8CoT detail level 7 ε = 0.184: 6.0CoT detail level 7 ε = 0.292: 3.8CoT detail level 7 ε = 0.340: 3.3CoT detail level 7 ε = 0.342: 4.2CoT detail level 7 ε = 0.433: 3.7CoT detail level 7 ε = 0.439: 4.0CoT detail level 7 ε = 0.497: 3.5CoT detail level 7 ε = 0.501: 6.7CoT detail level 7 ε = 0.679: 5.1CoT detail level 7 ε = 0.684: 6.8CoT detail level 7 ε = 0.933: 5.2CoT detail level 7 ε = 0.940: 5.9CoT detail level 7 ε = 0.993: 5.6CoT detail level 8 ε = 0.00100: 589.2CoT detail level 8 ε = 0.00194: 589.2CoT detail level 8 ε = 0.00196: 588.4CoT detail level 8 ε = 0.00215: 534.1CoT detail level 8 ε = 0.00237: 484.8CoT detail level 8 ε = 0.00261: 440.1CoT detail level 8 ε = 0.00288: 399.5CoT detail level 8 ε = 0.00317: 362.6CoT detail level 8 ε = 0.00350: 329.2CoT detail level 8 ε = 0.00385: 298.8CoT detail level 8 ε = 0.00424: 271.2CoT detail level 8 ε = 0.00467: 246.2CoT detail level 8 ε = 0.00518: 222.0CoT detail level 8 ε = 0.00575: 200.1CoT detail level 8 ε = 0.00638: 180.4CoT detail level 8 ε = 0.00708: 162.6CoT detail level 8 ε = 0.00785: 146.6CoT detail level 8 ε = 0.00877: 131.2CoT detail level 8 ε = 0.00979: 117.5CoT detail level 8 ε = 0.0110: 104.5CoT detail level 8 ε = 0.0124: 92.9CoT detail level 8 ε = 0.0140: 82.0CoT detail level 8 ε = 0.0160: 71.9CoT detail level 8 ε = 0.0184: 62.6CoT detail level 8 ε = 0.0212: 54.2CoT detail level 8 ε = 0.0247: 46.5CoT detail level 8 ε = 0.0292: 39.4CoT detail level 8 ε = 0.0350: 32.9CoT detail level 8 ε = 0.0424: 27.1CoT detail level 8 ε = 0.0526: 21.9CoT detail level 8 ε = 0.0665: 17.3CoT detail level 8 ε = 0.0871: 13.2CoT detail level 8 ε = 0.118: 9.8CoT detail level 8 ε = 0.169: 6.8CoT detail level 8 ε = 0.261: 4.4CoT detail level 8 ε = 0.340: 3.4CoT detail level 8 ε = 0.342: 4.5CoT detail level 8 ε = 0.407: 3.8CoT detail level 8 ε = 0.413: 4.3CoT detail level 8 ε = 0.497: 3.5CoT detail level 8 ε = 0.501: 6.9CoT detail level 8 ε = 0.679: 5.1CoT detail level 8 ε = 0.684: 7.5CoT detail level 8 ε = 0.830: 6.2CoT detail level 8 ε = 0.841: 6.6CoT detail level 8 ε = 0.993: 5.6CoT detail level 9 ε = 0.00100: 632.0CoT detail level 9 ε = 0.00194: 632.0CoT detail level 9 ε = 0.00196: 631.2CoT detail level 9 ε = 0.00215: 573.0CoT detail level 9 ε = 0.00237: 520.1CoT detail level 9 ε = 0.00261: 472.1CoT detail level 9 ε = 0.00288: 428.5CoT detail level 9 ε = 0.00317: 389.0CoT detail level 9 ε = 0.00350: 353.1CoT detail level 9 ε = 0.00385: 320.5CoT detail level 9 ε = 0.00424: 291.0CoT detail level 9 ε = 0.00467: 264.1CoT detail level 9 ε = 0.00515: 239.7CoT detail level 9 ε = 0.00571: 216.1CoT detail level 9 ε = 0.00634: 194.8CoT detail level 9 ε = 0.00703: 175.6CoT detail level 9 ε = 0.00780: 158.3CoT detail level 9 ε = 0.00871: 141.8CoT detail level 9 ε = 0.00973: 126.9CoT detail level 9 ε = 0.0109: 113.6CoT detail level 9 ε = 0.0122: 101.0CoT detail level 9 ε = 0.0137: 89.8CoT detail level 9 ε = 0.0156: 79.3CoT detail level 9 ε = 0.0178: 69.5CoT detail level 9 ε = 0.0204: 60.6CoT detail level 9 ε = 0.0236: 52.4CoT detail level 9 ε = 0.0276: 44.7CoT detail level 9 ε = 0.0326: 37.8CoT detail level 9 ε = 0.0390: 31.6CoT detail level 9 ε = 0.0477: 25.9CoT detail level 9 ε = 0.0591: 20.9CoT detail level 9 ε = 0.0753: 16.4CoT detail level 9 ε = 0.0993: 12.4CoT detail level 9 ε = 0.136: 9.1CoT detail level 9 ε = 0.198: 6.2CoT detail level 9 ε = 0.313: 4.0CoT detail level 9 ε = 0.340: 3.6CoT detail level 9 ε = 0.342: 4.5CoT detail level 9 ε = 0.430: 4.1CoT detail level 9 ε = 0.497: 3.5CoT detail level 9 ε = 0.501: 6.9CoT detail level 9 ε = 0.679: 5.1CoT detail level 9 ε = 0.684: 8.1CoT detail level 9 ε = 0.993: 5.6CoT detail level 10 ε = 0.00100: 632.0CoT detail level 10 ε = 0.00194: 632.0CoT detail level 10 ε = 0.00196: 631.2CoT detail level 10 ε = 0.00215: 573.0CoT detail level 10 ε = 0.00237: 520.1CoT detail level 10 ε = 0.00261: 472.1CoT detail level 10 ε = 0.00288: 428.5CoT detail level 10 ε = 0.00317: 389.0CoT detail level 10 ε = 0.00350: 353.1CoT detail level 10 ε = 0.00385: 320.5CoT detail level 10 ε = 0.00424: 291.0CoT detail level 10 ε = 0.00467: 264.1CoT detail level 10 ε = 0.00515: 239.7CoT detail level 10 ε = 0.00571: 216.1CoT detail level 10 ε = 0.00634: 194.8CoT detail level 10 ε = 0.00703: 175.6CoT detail level 10 ε = 0.00780: 158.3CoT detail level 10 ε = 0.00871: 141.8CoT detail level 10 ε = 0.00973: 126.9CoT detail level 10 ε = 0.0109: 113.6CoT detail level 10 ε = 0.0122: 101.0CoT detail level 10 ε = 0.0137: 89.8CoT detail level 10 ε = 0.0156: 79.3CoT detail level 10 ε = 0.0178: 69.5CoT detail level 10 ε = 0.0204: 60.6CoT detail level 10 ε = 0.0236: 52.4CoT detail level 10 ε = 0.0276: 44.7CoT detail level 10 ε = 0.0326: 37.8CoT detail level 10 ε = 0.0390: 31.6CoT detail level 10 ε = 0.0477: 25.9CoT detail level 10 ε = 0.0591: 20.9CoT detail level 10 ε = 0.0753: 16.4CoT detail level 10 ε = 0.0993: 12.4CoT detail level 10 ε = 0.136: 9.1CoT detail level 10 ε = 0.198: 6.2CoT detail level 10 ε = 0.313: 4.0CoT detail level 10 ε = 0.340: 3.6CoT detail level 10 ε = 0.342: 4.5CoT detail level 10 ε = 0.430: 4.1CoT detail level 10 ε = 0.497: 3.5CoT detail level 10 ε = 0.501: 6.9CoT detail level 10 ε = 0.679: 5.1CoT detail level 10 ε = 0.684: 8.1CoT detail level 10 ε = 0.993: 5.6
How CoT information scales with epsilon as trace detail varies.
02004006008001000Empirical sample complexity10⁰10⁻¹10⁻²10⁻³10⁻⁴
CoT-Cons, E2E errorE2E-Cons, E2E errorCoT-Cons, CoT errorE2E-Cons, CoT errorCoT-Cons, E2E error ε = 0.000100: 5CoT-Cons, E2E error ε = 0.000391: 5CoT-Cons, E2E error ε = 0.000399: 4CoT-Cons, E2E error ε = 0.00345: 4CoT-Cons, E2E error ε = 0.00351: 3CoT-Cons, E2E error ε = 0.0181: 3CoT-Cons, E2E error ε = 0.0185: 2CoT-Cons, E2E error ε = 0.0901: 2CoT-Cons, E2E error ε = 0.0918: 1CoT-Cons, E2E error ε = 1.00: 1CoT-Cons, CoT error ε = 0.000100: 10CoT-Cons, CoT error ε = 0.00141: 10CoT-Cons, CoT error ε = 0.00142: 5CoT-Cons, CoT error ε = 0.00422: 5CoT-Cons, CoT error ε = 0.00430: 4CoT-Cons, CoT error ε = 0.0239: 4CoT-Cons, CoT error ε = 0.0243: 3CoT-Cons, CoT error ε = 0.118: 3CoT-Cons, CoT error ε = 0.120: 2CoT-Cons, CoT error ε = 0.496: 2CoT-Cons, CoT error ε = 0.505: 1CoT-Cons, CoT error ε = 1.00: 1E2E-Cons, E2E error ε = 0.000100: 1000E2E-Cons, E2E error ε = 0.000101: 1000E2E-Cons, E2E error ε = 0.000102: 750E2E-Cons, E2E error ε = 0.000132: 750E2E-Cons, E2E error ε = 0.000133: 500E2E-Cons, E2E error ε = 0.000213: 500E2E-Cons, E2E error ε = 0.000215: 350E2E-Cons, E2E error ε = 0.000245: 350E2E-Cons, E2E error ε = 0.000247: 250E2E-Cons, E2E error ε = 0.000308: 250E2E-Cons, E2E error ε = 0.000311: 200E2E-Cons, E2E error ε = 0.000425: 200E2E-Cons, E2E error ε = 0.000429: 150E2E-Cons, E2E error ε = 0.000531: 150E2E-Cons, E2E error ε = 0.000535: 100E2E-Cons, E2E error ε = 0.000753: 100E2E-Cons, E2E error ε = 0.000760: 75E2E-Cons, E2E error ε = 0.00133: 75E2E-Cons, E2E error ε = 0.00135: 50E2E-Cons, E2E error ε = 0.00682: 50E2E-Cons, E2E error ε = 0.00688: 30E2E-Cons, E2E error ε = 0.0171: 30E2E-Cons, E2E error ε = 0.0173: 20E2E-Cons, E2E error ε = 0.0375: 20E2E-Cons, E2E error ε = 0.0379: 15E2E-Cons, E2E error ε = 0.0837: 15E2E-Cons, E2E error ε = 0.0845: 10E2E-Cons, E2E error ε = 0.177: 10E2E-Cons, E2E error ε = 0.178: 5E2E-Cons, E2E error ε = 0.229: 5E2E-Cons, E2E error ε = 0.233: 4E2E-Cons, E2E error ε = 0.265: 4E2E-Cons, E2E error ε = 0.270: 3E2E-Cons, E2E error ε = 0.337: 3E2E-Cons, E2E error ε = 0.343: 2E2E-Cons, E2E error ε = 0.413: 2E2E-Cons, E2E error ε = 0.420: 1E2E-Cons, E2E error ε = 1.00: 1E2E-Cons, CoT error ε = 0.955: 30E2E-Cons, CoT error ε = 0.964: 15E2E-Cons, CoT error ε = 0.973: 10E2E-Cons, CoT error ε = 0.982: 10E2E-Cons, CoT error ε = 0.991: 3E2E-Cons, CoT error ε = 1.00: 1
Empirical sample complexity for end-to-end versus CoT learning.
0.00.20.40.60.81.0
10⁰10¹10²10³
Sample size
CoT-Cons, E2E error, m = 1 0.488 (0.448–0.530)CoT-Cons, E2E error, m = 2 0.882 (0.852–0.908)CoT-Cons, E2E error, m = 3 0.972 (0.956–0.984)CoT-Cons, E2E error, m = 4 0.994 (0.986–1.000)CoT-Cons, E2E error, m = 5 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 10 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 15 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 20 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 30 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 50 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 75 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 100 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 150 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 200 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 250 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 350 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 500 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 750 1.000 (1.000–1.000)CoT-Cons, E2E error, m = 1000 1.000 (1.000–1.000)E2E-Cons, E2E error, m = 1 0.030 (0.018–0.046)E2E-Cons, E2E error, m = 2 0.068 (0.048–0.092)E2E-Cons, E2E error, m = 3 0.124 (0.096–0.154)E2E-Cons, E2E error, m = 4 0.146 (0.118–0.178)E2E-Cons, E2E error, m = 5 0.208 (0.172–0.244)E2E-Cons, E2E error, m = 10 0.428 (0.384–0.472)E2E-Cons, E2E error, m = 15 0.600 (0.556–0.646)E2E-Cons, E2E error, m = 20 0.666 (0.626–0.708)E2E-Cons, E2E error, m = 30 0.740 (0.700–0.776)E2E-Cons, E2E error, m = 50 0.804 (0.768–0.838)E2E-Cons, E2E error, m = 75 0.808 (0.774–0.840)E2E-Cons, E2E error, m = 100 0.862 (0.830–0.894)E2E-Cons, E2E error, m = 150 0.840 (0.806–0.870)E2E-Cons, E2E error, m = 200 0.878 (0.850–0.906)E2E-Cons, E2E error, m = 250 0.900 (0.872–0.926)E2E-Cons, E2E error, m = 350 0.902 (0.874–0.930)E2E-Cons, E2E error, m = 500 0.942 (0.922–0.960)E2E-Cons, E2E error, m = 750 0.960 (0.940–0.976)E2E-Cons, E2E error, m = 1000 0.984 (0.972–0.994)CoT-Cons, CoT error, m = 1 0.398 (0.352–0.440)CoT-Cons, CoT error, m = 2 0.848 (0.818–0.880)CoT-Cons, CoT error, m = 3 0.968 (0.952–0.980)CoT-Cons, CoT error, m = 4 0.994 (0.986–1.000)CoT-Cons, CoT error, m = 5 0.998 (0.994–1.000)CoT-Cons, CoT error, m = 10 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 15 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 20 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 30 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 50 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 75 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 100 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 150 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 200 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 250 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 350 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 500 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 750 1.000 (1.000–1.000)CoT-Cons, CoT error, m = 1000 1.000 (1.000–1.000)E2E-Cons, CoT error, m = 1 0.000 (0.000–0.000)E2E-Cons, CoT error, m = 2 0.000 (0.000–0.000)E2E-Cons, CoT error, m = 3 0.004 (0.000–0.010)E2E-Cons, CoT error, m = 4 0.002 (0.000–0.006)E2E-Cons, CoT error, m = 5 0.002 (0.000–0.006)E2E-Cons, CoT error, m = 10 0.012 (0.004–0.024)E2E-Cons, CoT error, m = 15 0.022 (0.010–0.034)E2E-Cons, CoT error, m = 20 0.012 (0.004–0.022)E2E-Cons, CoT error, m = 30 0.028 (0.014–0.042)E2E-Cons, CoT error, m = 50 0.018 (0.008–0.030)E2E-Cons, CoT error, m = 75 0.014 (0.004–0.024)E2E-Cons, CoT error, m = 100 0.020 (0.008–0.034)E2E-Cons, CoT error, m = 150 0.016 (0.006–0.030)E2E-Cons, CoT error, m = 200 0.012 (0.004–0.024)E2E-Cons, CoT error, m = 250 0.018 (0.008–0.032)E2E-Cons, CoT error, m = 350 0.024 (0.012–0.038)E2E-Cons, CoT error, m = 500 0.018 (0.008–0.032)E2E-Cons, CoT error, m = 750 0.020 (0.008–0.034)E2E-Cons, CoT error, m = 1000 0.018 (0.008–0.030)
Probability that each learning rule achieves zero error as the sample size grows.

In this setting, the theoretical IDCoT(ε;H)/ε+\cotinfodomain{\mathcal{D}}(\epsilon; \mathcal{H}) / \epsilon^+ curve approaches ≈600\approx 600 as ε→0\epsilon \to 0, forecasting an improvement on the order of 600× to learn h⋆\hstar with very small error. Empirical results confirm dramatic gains: between 10210^2 and 10310^3 times fewer samples are needed under CoT supervision to reach equivalent accuracy. This demonstrates that CoT information can yield orders-of-magnitude improvements in sample efficiency, depending on how much structure the reasoning trace exposes about the underlying computation.

Conclusion

This work develops a learning theory framework for understanding the statistical advantage of chain-of-thought supervision. By introducing the notion of CoT information, we provide an information-theoretic measure that quantifies how observing reasoning traces accelerate learning. The main results establish upper bounds on sample complexity in terms of the CoT information, together with information-theoretic lower bounds. Together, these results suggest that CoT information is a fundamental measure of the statistical complexity of learning under CoT supervision. Empirical simulations confirm these predictions, demonstrating substantial gains—sometimes by orders of magnitude—when reasoning traces align with the underlying computation.

Related
PaperThis page

CoT Information: Improved Sample Complexity under Chain-of-Thought Supervision

reasoninglanguage modelslearning theory

A statistical learning theory for chain-of-thought supervision, centered on a CoT information measure that governs sample complexity.

Cite
@inproceedings{altabaa2025cotinformation,
  title={CoT Information: Improved Sample Complexity under Chain-of-Thought Supervision},
  author={Awni Altabaa and Omar Montasser and John Lafferty},
  booktitle={The Thirty-ninth Annual Conference on Neural Information Processing Systems},
  year={2025},
  url={https://openreview.net/forum?id=OkVQJZWGfn}
}